Jev for LLM Evaluations
Continue with the workshop writeup
Open the canonical pages, recording, materials, and code repo.
In the batch and flex workshop we built an eval for the FAQ agent and scored it with an LLM judge. Here we swap that judge for Jev, a model that returns typed decisions instead of generating text. We keep the same eval, ten agent answers with their tool calls and three good/bad checks each. One Jev request scores all three checks for one answer. On our ten-entry run it cost $0.000429 while the OpenAI judge cost $0.02439, about 57 times cheaper.
Jev is TypeSafe AI's decision model. It reads a piece of application state and returns a class per question. It generates no output tokens, so there's no output-token cost and no wait for streaming text. We ask a judge only to say good or bad, and Jev is built for exactly that.
We keep the OpenAI judge as the baseline and add a Jev judge through OpenRouter's decisions API. The same checks also run through Laya, an open-weights decision model that runs locally on a CPU.
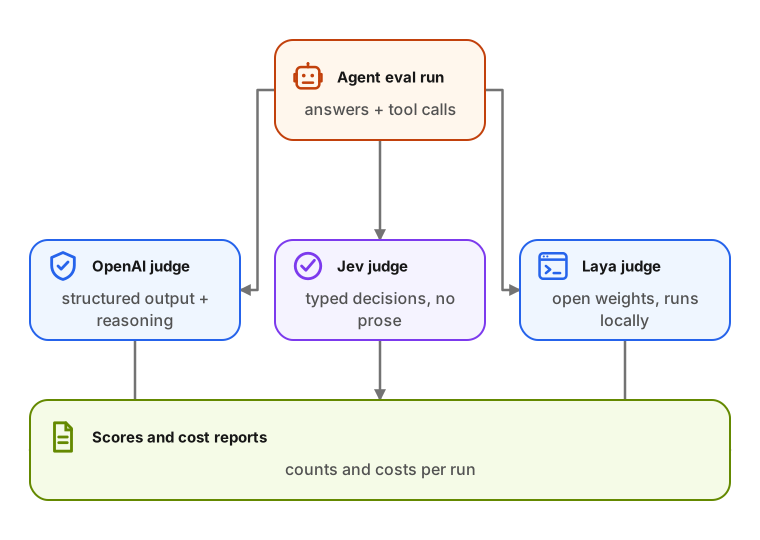
All three judges score the same run, so we can compare verdicts and costs directly. On our sample they agree almost everywhere. All three mark the same answer incorrect, and Jev and Laya return identical scores on every check.
We dictated most of the code as prompts to an AI assistant. We include the prompts, so you can reproduce the workflow with any agent you like. We tried one approach that didn't work: batching ten records into one request by making state an array. It looks natural, but the model returns one mixed answer. The final code sends one request per entry and runs them concurrently.
Links
Resources used here:
- Saving Money with Batch and Flex - the eval framework we port from.
- End-to-End Agent Deployment - the FAQ agent we evaluate.
- Jev on OpenRouter - the model page, with pricing and the decisions API.
- Laya - the open-weights decision model we run locally.
Hosted by
Alexey Grigorev
Chief Agent Officer at AI Shipping Labs
Software engineer and machine learning practitioner with 15+ years of experience building production ML systems. I focus on practical, production-grade ML and AI systems, from early prototypes to reliable systems in production.
I'm the founder of DataTalks.Club, a free community that connects tens of thousands of practitioners worldwide, and the creator of the Zoomcamp series, free, code-first programs that have reached 100,000+ learners globally.
At AI Shipping Labs, I'm building the kind of environment that would have accelerated my own career growth. After years of teaching at scale, I wanted something more focused: a space for action-oriented builders who want to turn AI ideas into real projects. The community gives members the structure, accountability, and peer support to ship practical AI products consistently, even alongside their main jobs.
Related content
AI Engineering Buildcamp: From RAG to Agents
A hands-on course on building production AI applications with large language models: retrieval-augmented generation (RAG), structured output, AI agents, testing, monitoring, and e…
AI Hero: 7-Day AI Agents Crash-Course
Build a complete AI agent from data ingestion to deployment in 7 focused days. You will use a real GitHub repository as the source material, then build an assistant that can read …
Setting Up a Remote Environment for Agentic Workloads
A remote development box gives coding agents a stable place to run while you disconnect, reconnect, or change devices. We set up an Ubuntu server, protect SSH access, install the …
September 1, 2026